perf sched —— 调度器分析完全指南
perf sched 是 perf 的调度器专用子命令,基于内核 sched:* tracepoint 记录每一次调度事件,回答:"每个线程等了多久 CPU、为什么被切走、谁在抢 CPU"。
关联:scheduling-observation(调度行为宏观观察)、scheduling(CFS 调度器原理)、context-switch(上下文切换开销)
一、perf sched 能回答什么问题
| 问题 | 用什么 | 输出含义 |
|---|---|---|
| 哪个线程等待 CPU 时间最长? | perf sched latency | 每线程的 avg/max 调度延迟 |
| 线程频繁切换吗?谁和谁在来回切? | perf sched timehist | 逐次切换带 CPU 和时间线 |
| 某线程老被抢 CPU,还是自己让出去的? | perf sched timehist + 看 reason | wakeup vs preempt |
| CPU 上有没有"调度空洞"(没人跑)? | perf sched timehist 的 visual aid | 空白段 = idle |
| 线程在核间反复迁移吗? | perf sched timehist -w | 迁移事件 + 各核时间线并列 |
| 调度事件的完整 timeline 是什么? | perf sched script | 原始事件清单,适合脚本处理 |
二、核心子命令速览
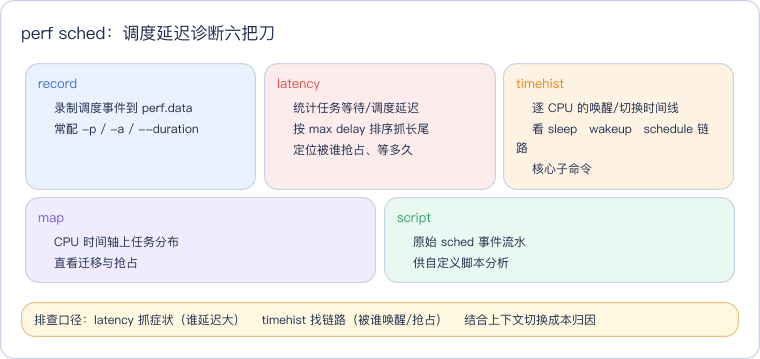
perf sched record      # 录制调度事件(sched:sched_switch, sched:sched_wakeup 等)
perf sched latency     # 从录制数据分析"每个 task 等了多久才拿到 CPU"
perf sched timehist    # 从录制数据分析"时间线上谁在跑、谁在等、为什么切换"
perf sched map         # 可视化调度器在各 CPU 上的行为(需可视化工具)
perf sched script      # 原始事件 dump,适合脚本/管道处理
perf sched replay # 回放录制时的调度决策(开发/调试用)三、perf sched record —— 录制调度事件
# 录制全系统 30 秒
perf sched record -a -- sleep 30
# 录制指定进程
perf sched record -p <PID> -- sleep 30
必须带 duration 控制:调度事件密度极高(每秒数千到数万次),不加 -- sleep N 会无限录制直到 Ctrl+C,产生巨大的 perf.data。
录制了什么:核心是 sched:sched_switch(prev task → next task)和 sched:sched_wakeup(task 唤醒),附带 sched:sched_migrate_task(跨核迁移)、sched:sched_wakeup_new(新线程首调度)等。
四、perf sched latency —— 调度延迟分析
4.1 基本使用
perf sched record -a -- sleep 30
perf sched latency
4.2 输出解读
  -----------------------------------------------------------------------------------------------------------------
  Task                  |   Runtime ms  | Switches | Avg delay ms    | Max delay ms    | Max delay start     | Max delay end       |
  -----------------------------------------------------------------------------------------------------------------
  cpu_demo:4043         |    4873.245   |      15  |       0.058     |       2.340     |  18245.123456       |  18247.463456       |
  kworker/1:0:56        |       2.103   |      42  |       0.012     |       0.089     |  18246.789012       |  18246.878012       |
  sshd:1234             |     125.678   |     430  |       0.031     |       5.234     |  18250.111111       |  18255.345111       |
nginx:5678 | 890.234 | 2300 | 0.042 | 12.345 | 18248.222222 | 18260.567222 || 列 | 含义 | 如何判断 |
|---|---|---|
| Runtime ms | 录制期间该 task 实际跑在 CPU 上的总时间 | 越大 = 占用 CPU 越多(计算型),越小 = IO/锁竞争型 |
| Switches | 该 task 被调度进入的次数 | 总时间 ÷ 切换次数 ≈ 每次运行时长(10ms 为典型时间片) |
| Avg delay ms | 从"被唤醒(wakeup)"到"真正拿到 CPU(sched_switch in)"的平均等待 | < 0.1ms = 健康;> 1ms = 需关注;> 10ms = 严重 |
| Max delay ms | 最大的单次调度延迟 | 这是长尾——某个时刻该 task 被严重延迟 |
| Max delay start/end | 最大延迟发生的时间戳 | 可结合 perf sched timehist 定位当时谁在占 CPU |
4.3 诊断模式
Avg delay < 0.1ms, Max delay < 1ms   → 调度健康,CPU充裕
Avg delay < 0.5ms, Max delay 10ms+   → 偶发长尾,存在瞬时CPU争抢
Avg delay > 1ms                       → 持续CPU竞争,任务长期排队
Avg delay > 10ms                      → 严重过载,实时性崩溃
对比 Runtime 和 Switches:
| Runtime | Switches | 每次运行 | 程序类型 |
|---|---|---|---|
| 大(>1s) | 少(<100) | >10ms | 纯计算,很少被打断 |
| 大 | 多(>1000) | <5ms | 计算+频繁切换,可能是锁竞争 |
| 小(<100ms) | 少 | <5ms | IO 型,大部分时间在阻塞 |
| 小 | 多 | <1ms | 事件驱动高频短任务 |
五、perf sched timehist —— 时间线分析(核心)
timehist 比 latency 更强大——它不是只给汇总统计,而是逐次展示每次切换的时间线,相当于"调度器日志的可视化"。
5.1 基本使用
perf sched record -a -- sleep 10
perf sched timehist
5.2 输出格式
           time    cpu  task name              wait time  sch delay   run time
                         [tid/pid]                (msec)     (msec)     (msec)
--------------- ------  --------------------  ---------  ---------  ---------
18245.123456 [0000]  cpu_demo[4043]             0.058      0.002      4.567
18245.123789 [0001]  nginx[5678/5678]           0.031      0.001      0.234
18245.124023 [0002]  <idle>                       -          -        0.234
18245.124456 [0003]  kworker/3:0[87]            0.012      0.003      0.567
18245.128023 [0000]  sshd[1234/1234]            0.120      0.001      0.089
18245.128112 [0000]  cpu_demo[4043]             0.003      0.001     10.345
...| 列 | 含义 |
|---|---|
| time | 调度事件发生的绝对时间戳(秒,纳秒精度) |
| cpu | 在哪个 CPU 核上 |
| task name[tid/pid] | task 名、线程 ID、进程 ID |
| wait time | 该 task 从 woken up 到实际进入 CPU 的等待时间(调度延迟) |
| sch delay | 调度器自身的耗时(context_switch 实际耗时) |
| run time | 该 task 这次跑了多久才被切走(或主动让出) |
5.3 实用选项
# -w: 显示唤醒关系——谁唤醒了谁
perf sched timehist -w
# -M <cpu>: 只看指定 CPU 的时间线
perf sched timehist -M 0,1
# -p <PID>: 只看指定进程
perf sched timehist -p <PID>
# -V: 加 visual aid——CPU 的时间线可视化
perf sched timehist -V
# 只看唤醒事件(wakeup)
perf sched timehist --state
# 汇总模式:不逐行输出,仅给统计数据
perf sched timehist -s
5.4 -w 唤醒链分析
perf sched timehist -w time cpu task name wait time sch delay run time
[tid/pid] (msec) (msec) (msec)
--------------- ------ -------------------- --------- --------- ---------
18245.123456 [0000] cpu_demo[4043] 0.058 0.002 4.567
awakened: kworker[87]
...最后一列 awakened: 显示了是谁唤醒了这个 task。用于追踪事件链:网络包到了 → ksoftirqd 唤醒 → epoll_wait 返回 → 用户线程被唤醒。
5.5 -s 汇总模式
perf sched timehist -sRuntime summary
comm parent sched-in run-time min-run avg-run max-run stddev migrations switches
(count) (msec) (msec) (msec) (msec) % % %
cpu_demo[4043] cpu_demo[4043] 15 4873.245 0.078 324.883 4012.345 0 0 15
nginx[5678] nginx[5678] 2300 890.234 0.012 0.387 12.345 1 5 2300| 列 | 含义 |
|---|---|
| sched-in | 被调度进入 CPU 的次数(= Switches) |
| min-run/avg-run/max-run | 每次运行的最短/平均/最长时间 |
| migrations % | 跨核迁移比例(> 5% 需关注) |
| switches | 总切换次数 |
六、perf sched map —— 可视化调度行为
perf sched map 输出一个 ASCII 文本图,展示各 CPU 上 task 的切换情况。
perf sched map输出示例:
            *A0            448264.715732 secs A0 => cpu_demo:4043
            *.             448264.715735 secs .  => swapper:0
            *A0  B0 .  .   448264.715738 secs B0 => nginx:5678
            *A0  B0  C0 .  448264.715740 secs C0 => kworker:87
            *A0  *.  C0 .  448264.715895 secs B0 切走 (B0 runtime 0.157ms)
            *.   .   C0 .  448264.715990 secs A0 切走
每列一个 CPU,* 表示该 CPU 当前 idle,A0/B0 等为 task 标记。适合看"哪些 CPU 在空闲、哪些在忙、任务是否在漂移"。
对延迟敏感型应用,
perf sched map能直观看到"忙等线程霸占 CPU"还是"IDLE 期间没人干活"。
七、perf sched script —— 原始事件流水
# 输出所有调度事件的脚本格式
perf sched scriptcpu_demo 4043 [000] 18245.123456: sched:sched_switch: prev_comm=cpu_demo prev_pid=4043 prev_state=S ==> next_comm=sshd next_pid=1234
sshd 1234 [000] 18245.123545: sched:sched_switch: prev_comm=sshd prev_pid=1234 prev_state=R ==> next_comm=cpu_demo next_pid=4043prev_state 含义:
- R:可运行(时间片到了,被抢占)
- S:睡眠(主动让出——等 IO / 锁 / sleep)
- D:不可中断睡眠(等磁盘 IO)
用 grep / awk 分析原始事件:例如
grep "prev_state=D"找出所有 D 状态切换(说明在等磁盘/IO)。
八、实战场景
场景 1:判断程序是 CPU 型还是 IO 型
perf sched record -p <PID> -- sleep 10
perf sched timehist -s -p <PID>
看 avg-run:
- avg-run > 5ms + switches 少 → CPU 型,拿到 CPU 就一直跑
- avg-run < 0.1ms + switches 多 → IO/锁型,频繁阻塞
场景 2:定位哪个线程抢 CPU 导致他人长尾延迟
perf sched record -a -- sleep 30
perf sched latency
找到 Max delay 最大的受害者线程,记录其 Max delay start/end 时间点。再在这个时间附近看:
perf sched timehist -V
# 或用 script 过滤该时间窗口
perf sched script | awk '$1 > 18245.123 && $1 < 18247.463'
找出该时间窗口内哪个线程在占着 CPU。
场景 3:检查实时任务是否饿死普通任务
perf sched latency | sort -t ':' -k3 -n -r | head -20
# 按 Max delay 降序排列,找出等最久的受害者
如果某些 task 的 Max delay > 100ms,检查抢占者:perf sched timehist -V 看谁在长时间占据 CPU,再用 chrt -p 确认其优先级。
场景 4:NUMA 迁移分析
perf sched timehist -s
# 看 migrations % 列
如果某线程 migrations % > 10%,说明调度器频繁将其搬到其他核。结合 numastat 确认是否在跨 NUMA 节点搬(远程访问延迟高),必要时 taskset 绑核。
场景 5:找出"频繁唤醒→跑很短→立即睡眠"的线程
perf sched timehist -s | sort -t '|' -k5 -n | head -10
# 按 min-run 升序,找出每次只跑极短时间的线程
如果看到 min-run < 0.001ms(1μs 级别),说明线程几乎拿到 CPU 立刻让出——极端的锁竞争或自旋等待(sched_yield)。
九、与其他工具的配合
| 步骤 | 工具 | 目的 |
|---|---|---|
| ① 宏观 | vmstat 1 / mpstat -P ALL | 看 r 队列、cs 切换速率、逐核 CPU 分布 |
| ② 线程级 | pidstat -t -w -u 1 | 看每个线程的 cswch/nvcswch、CPU 核迁移 |
| ③ 调度深度 | perf sched latency | 量化每线程的等待延迟 |
| ④ 时间线 | perf sched timehist -V | 定位具体时刻谁占 CPU |
| ⑤ 热点定位 | perf record -g -t <TID> | 找到占用 CPU 的函数 |
十、注意事项
- 录制时间要短:调度事件极密,30 秒的
perf.data可能几十 MB,timehist输出可达数万行。先-s看汇总,需要时再逐行分析。 - 需要 root 权限:
sched:sched_switch等 tracepoint 通常需要root或CAP_PERFMON。 - 大数据量用
-s汇总:不要让timehist无过滤输出几万行到终端——先用-s汇总找到异常线程,再用-p <PID>过滤。 perf sched latency的延迟定义:它是sched_wakeup到sched_switch(next=该 task) 的时间差,即"从被唤醒到真正拿到 CPU 的等待时间"。不包含该 task 主动 sleep 的时间。- 高负载下的数据量:如果
cs> 10 万/s(上下文切换极频繁),建议录制时间 ≤ 5 秒。
十一、关键指标速查
| 指标 | 来源 | 健康 | 异常 |
|---|---|---|---|
| 平均调度延迟 | perf sched latency avg delay | < 0.1ms | > 1ms |
| 最大调度延迟 | perf sched latency max delay | < 1ms | > 10ms(长尾尖峰) |
| 每次运行平均时长 | perf sched timehist -s avg-run | > 1ms | < 0.1ms(频繁切出) |
| 跨核迁移比例 | perf sched timehist -s migrations % | < 3% | > 10% |
| 调度器自身耗时 | perf sched timehist sch delay | < 5μs | > 50μs(内核 bug 或异常中断) |
| prev_state | perf sched script | R/S | D → 不可中断等待(等 IO) |
十二、一句话总结
perf sched latency定量回答"谁等得最久",perf sched timehist -V可视化回答"那个瞬间谁在占 CPU",两者配合从调度角度完整还原一个多线程程序的"CPU 使用权争夺战"。