files_struct —— 进程的打开文件表(fd → file → inode 三层)
这是 task-struct 里
task->files那一项的展开。你每次open/socket/pipe拿到的那个文件描述符(fd),背后是内核的三层结构:files_struct(每进程的 fd 数组)→struct file(打开文件描述,存偏移)→inode(文件本体)。这三层的分工,直接决定了dup、fork、多线程共享 fd 的行为。本篇讲透files_struct内部结构、fdtable动态扩容算法、struct file的完整字段表、fd 分配机制、生命周期、以及相关的坑。
零、一句话认知:fd 只是一个数组下标,真正的状态在下面两层
文件描述符(fd)不是文件,它只是 files_struct 里那个数组的下标(0、1、2、3…)。下标指向的 struct file 才存着"读到哪了(偏移)、以什么模式打开";file 再指向 inode(磁盘上的文件本体)。
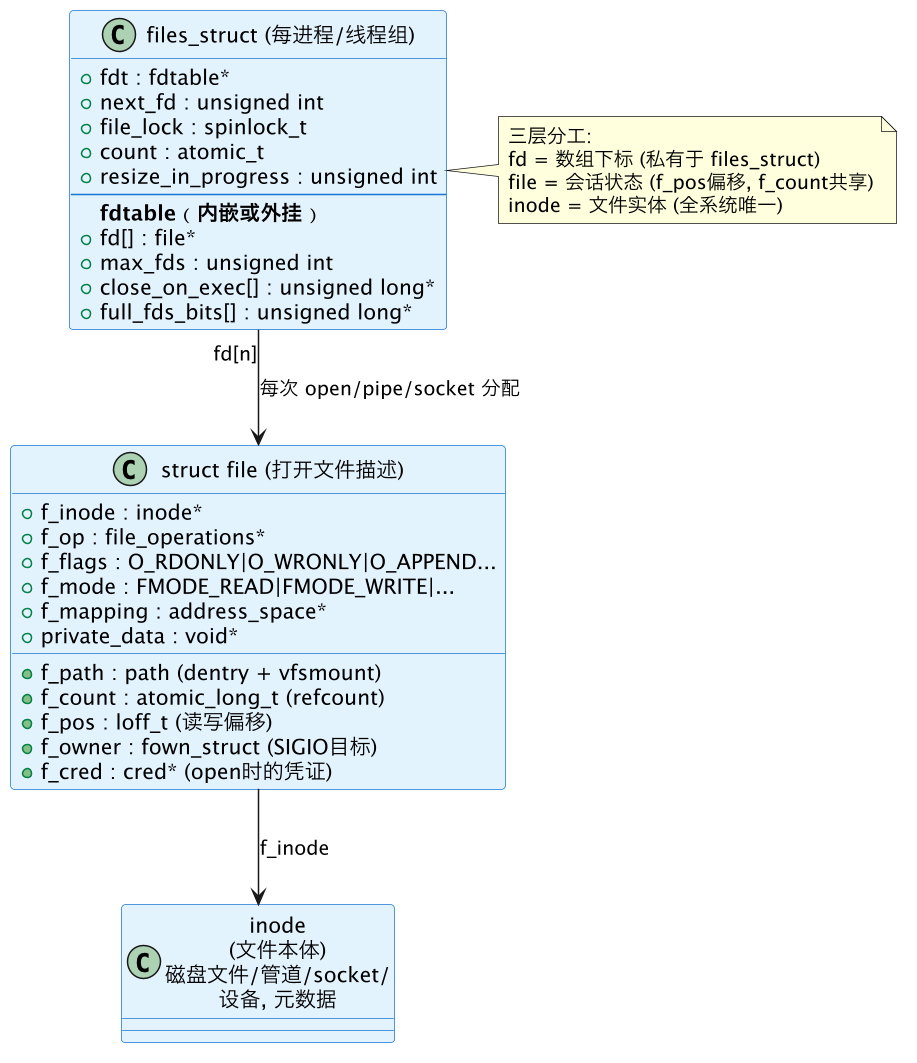
核心记忆:三层——fd(进程私有下标)→ file(会话状态,含偏移 f_pos + 引用计数 f_count)→ inode(文件本体)。关键洞察:偏移量(f_pos)在 file 这一层,不在 fd、也不在 inode。所以"共享同一个 file"就意味着"共享读写偏移",这是理解 dup/fork 的钥匙。
一、files_struct 内部结构
1.1 核心字段分组
files_struct 字段不多,但每一组都对应一个核心语义:
| 分组 | 字段 | 作用 |
|---|---|---|
| fd 表指针 | fdt | 指向 struct fdtable(fd 数组 + close_on_exec 位图 + 容量字段),初始内嵌在 files_struct 末尾,扩容后外挂 |
| 分配缓存 | next_fd | 记录上次分配到的 fd 号,下次从这里开始找空闲位——绝大多数情况下找空闲位是 O(1) |
| 并发保护 | file_lock | 自旋锁,保护 fd 表分配/释放/扩容(不和 f_pos 的锁混淆) |
| 引用计数 | count | files_struct 本身的引用计数——CLONE_FILES 的线程共享同一份,count > 1 意味着改动(如扩容)必须 COW |
| 扩容标志 | resize_in_progress | 扩容时置位,阻止并发扩容;也用 RCU 保证读侧安全 |
1.2 fdtable —— 藏在 files_struct 里或挂在外面
每个 files_struct 都有一个 struct fdtable,这是 fd 数组的真正容器:
三个关键字段的解释:
| 字段 | 含义 | 示例 |
|---|---|---|
fd[max_fds] | struct file * 指针数组,fd[n] == NULL 表示 fd n 空闲 | fd[0]=stdin, fd[5]=NULL(空闲) |
close_on_exec[] | 位图,bit n = 1 表示 fd n 设置了 FD_CLOEXEC,execve 时自动关闭 | close_on_exec[3] 的第 3 位 = 1 → execve 时关闭 fd 3 |
full_fds_bits[] | 位图,bit n = 1 表示 fd[n..n+63] 这一段全满——加速"找下一个空闲位"的跳过逻辑 | 如果 fd 32~95 全满,full_fds_bits[0] bit 0 = 1(跳过这一整段) |
full_fds_bits的巧妙之处:64 位的 unsigned long 可以一次跳过 64 个连续的 fd。当进程开到几千个 fd 时,逐位扫描fd[]数组太慢——full_fds_bits让find_next_zero_bit只扫描高层次的位图,命中后再精细查找对应区段。
1.3 fd 分配算法 —— 怎么找到最小的未用 fd
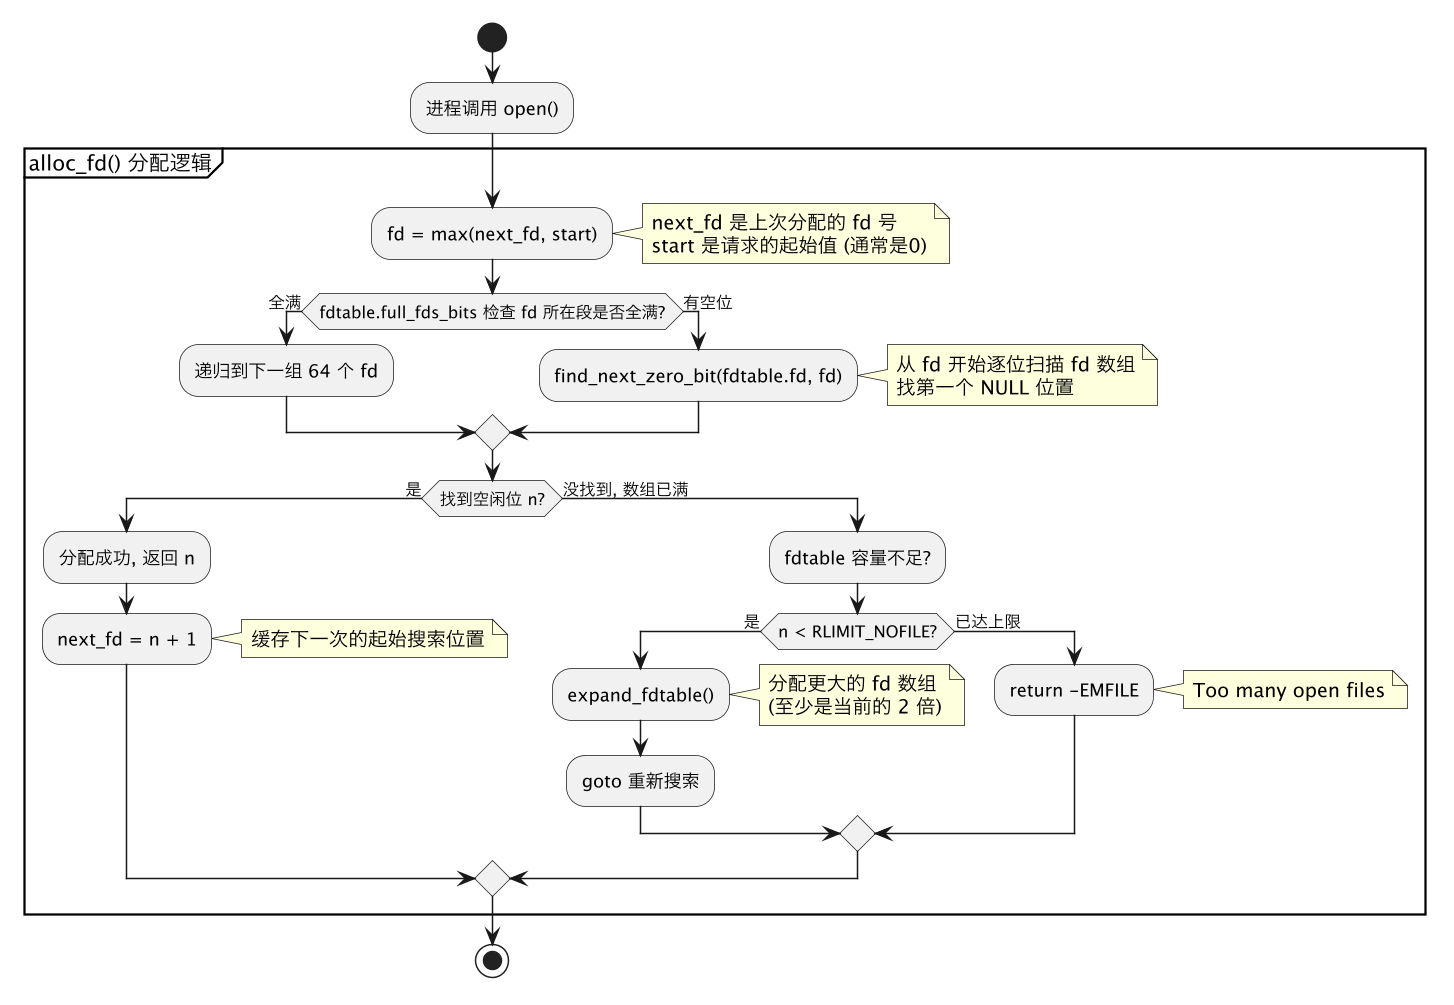
每次 open/socket/pipe/accept 都要从 files_struct 里找一个空闲 fd。内核的分配算法在 fs/file.c:alloc_fd() 中:
关键要点:
next_fd优化:普通进程的 fd 分配是单调递增的——每分配一个,next_fd就往前挪一格。随后close释放掉的 fd 虽然会变成空洞,但next_fd不会回退。只有当进程频繁开合 fd 时才需要从头扫描。start参数:dup2(fd, newfd)指定起始位置,open从 0 开始。这就是为什么fd=0(stdin)一旦被 close,下一个open就会占了 stdin 的位置。- 扩容触发:
alloc_fd发现fdtable.max_fds不够时调用expand_fdtable(),至少翻倍。详见 §二。
二、fdtable 动态扩容 —— 从 64 到数十万 fd
2.1 扩容的三阶段
files_struct 的 fd 表分三个阶段:
阶段 1: 内嵌 fdtable(初始)
  files_struct 结构体末尾有一个嵌入式 fdtable,max_fds=64
  → 前 64 个 fd 不触发任何内存分配
阶段 2: 小规模扩容(≤ NR_OPEN_DEFAULT = BITS_PER_LONG, 64)
  expand_fdtable() → 分配 fd 数组 + close_on_exec + full_fds_bits 三个数组
  → 此时 fdtable 结构体可能仍在 files_struct 内(取决于编译布局)
阶段 3: 大规模扩容(> 64)
  expand_fdtable() → 分配全新的 fdtable 结构体 + 三个大数组
  → fdt 指针指向独立分配的 fdtable,旧数组 free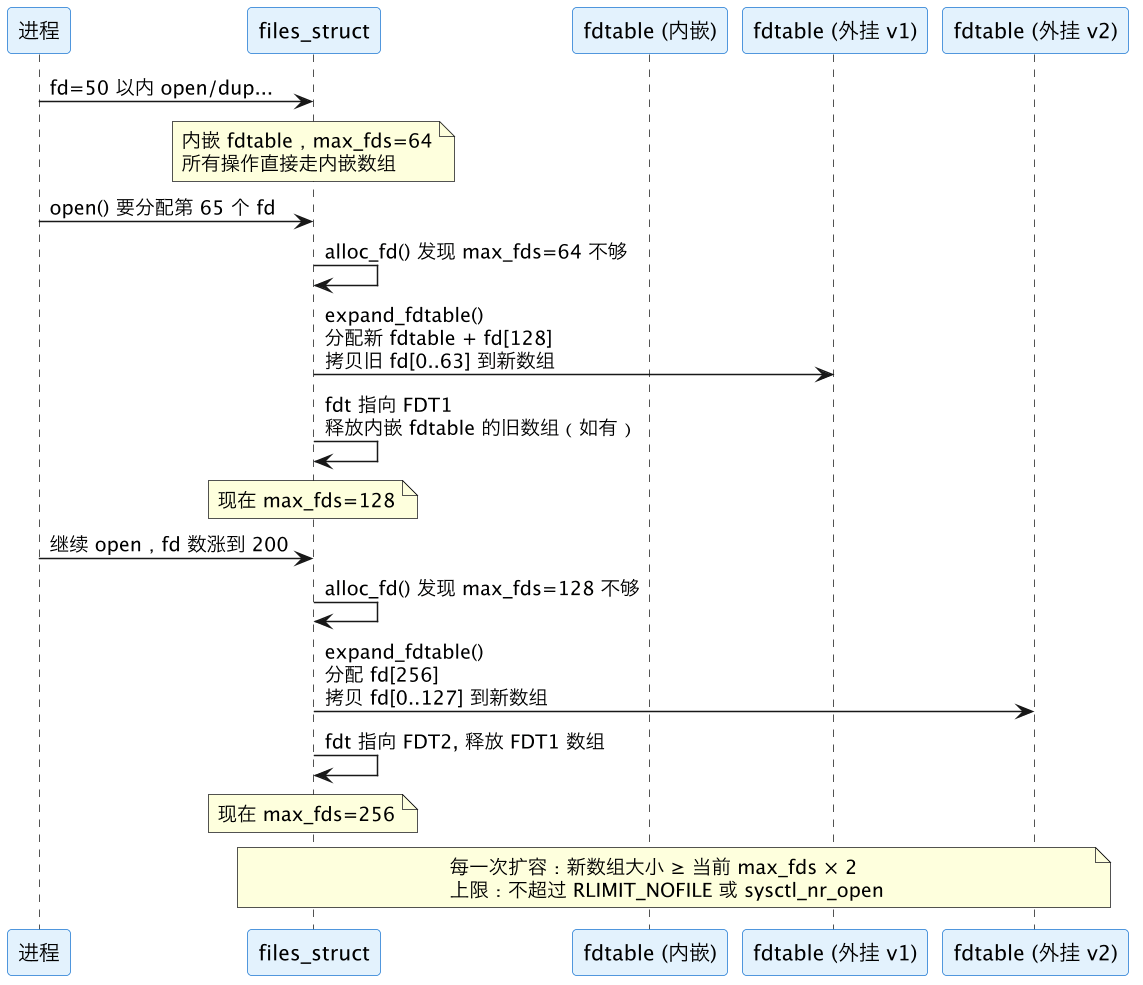
2.2 扩容时的 COW 保护
当 files_struct->count > 1(多个线程共享同一份)时,扩容不能直接修改共享结构——必须先 COW 分裂:
expand_fdtable()
  → if files_struct->count > 1:
        dup_fd(files_struct)   // 复制一份独立的 files_struct
        → 分配新 files_struct + 新 fdtable + 新 fd 数组
        → 拷贝所有 fd 指针(指向同一批 struct file)
        → 旧 files_struct->count--,新 count = 1
        → task->files = new_files_struct
  → 然后在独占的 files_struct 上扩容
这就是为什么多线程程序频繁 open 时会触发隐式的 fd 表拷贝——每个线程虽然共享 files_struct,但扩容时拿到独占副本。
2.3 RCU 保护:为什么扩容不锁读
fdtable 用 RCU 保护读侧:扩容时分配新数组、更新指针,正在读取的线程看到的要么是旧数组(完整),要么是新数组(完整),不会看到半初始化状态。对应的读侧代码在 include/linux/fdtable.h 中:
// 经典读侧模式:rcu_dereference + files_lookup_fd_raw
static inline struct file *files_lookup_fd_raw(struct files_struct *files, unsigned int fd)
{
    struct fdtable *fdt = rcu_dereference_raw(files->fdt);
    if (fd < fdt->max_fds)
        return rcu_dereference_raw(fdt->fd[fd]);
    return NULL;
}
expand_fdtable 扩容时是 rcu_assign_pointer(files->fdt, new_fdt),旧 fdtable 在 RCU Grace Period 结束后通过 call_rcu / kfree_rcu 释放。
三、struct file —— 打开文件的"会话层"
3.1 完整字段表
struct file 是 Linux 中最关键也最常用的结构体之一。它不是 VFS 层概念(不在 inode/superblock 那条继承链上),而是每次 open(或 pipe/socket 等创建函数)独立分配的一个会话对象:
| 字段 | 类型 | 作用 | 重要程度 |
|---|---|---|---|
f_path | struct path | 包含 dentry* 和 vfsmount*,定位文件在 VFS 中的路径 | ★★★ |
f_inode | struct inode* | 指向文件本体——file->f_path.dentry->d_inode 的快捷缓存 | ★★★ |
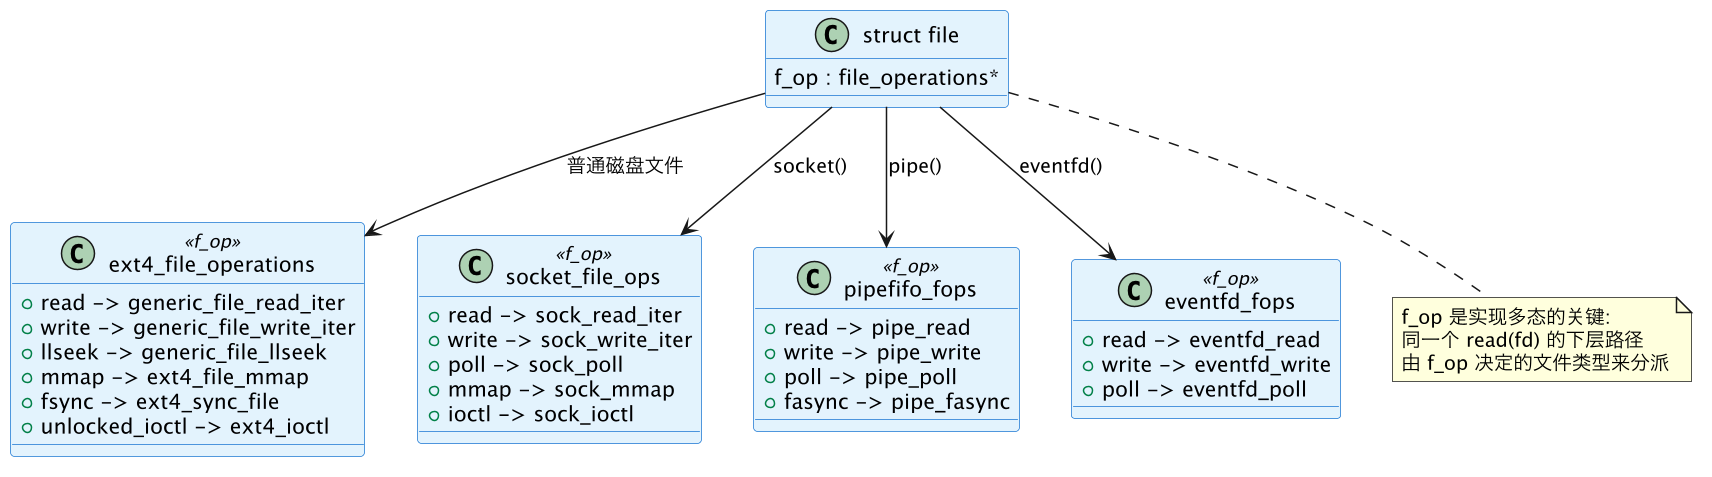
f_op | struct file_operations* | 函数虚表:read/write/llseek/mmap/ioctl/poll/... 每种文件类型不同实现 | ★★★ |
f_count | atomic_long_t | 引用计数:dup/fork 时 +1,close 时 -1,归零释放整个 struct file | ★★★ |
f_pos | loff_t | 读写偏移——read()/write() 后自动前移。dup 共享 file → 共享此偏移 | ★★★ |
f_flags | unsigned int | 打开标志:O_RDONLY/O_WRONLY/O_RDWR/O_APPEND/O_NONBLOCK/O_SYNC/... | ★★ |
f_mode | fmode_t | 内核内部模式位:FMODE_READ/FMODE_WRITE/FMODE_LSEEK/... 比 f_flags 更底层 | ★★ |
f_mapping | struct address_space* | 页缓存映射——read()/write() 最终操作 f_mapping 的 page。socket 指向 sock 关联的 mapping | ★★★ |
private_data | void* | 各子系统私有上下文——pipe 放 pipe_inode_info*,socket 放 socket*,epoll 放 eventpoll*,eventfd 放 eventfd_ctx*。这是 struct file 能"伪装"成任何东西的魔法 | ★★★ |
f_owner | struct fown_struct | SIGIO 信号所有者(pid/uid/tid),由 fcntl(F_SETOWN) 设置 | ★ |
f_cred | const struct cred* | open 时调用者的凭证——权限检查依据。即使 chown 了文件,已打开 fd 仍以 f_cred 检查 | ★★ |
f_ra | struct file_ra_state | readahead(预读)状态机——f_mapping 之外的独立预读上下文 | ★ |
f_lock | spinlock_t | 保护 f_pos/f_owner 等字段的并发访问(不保护 I/O 本身) | ★ |
f_ep | struct epitem* 链表 | 该 file 上挂的 epoll 监控项链表头(file → 被哪些 epoll fd 监控着) | ★★ |
f_tfile_llink | struct list_head | 链接到 superblock 的 "被打开文件" 链表 | ★ |
3.2 f_op —— 每种文件类型的"方法表"
f_op 是 struct file 的灵魂——它让同一个 read(fd, buf, n) 系统调用,对磁盘文件走 ext4_file_operations,对 socket 走 socket_file_ops,对 pipe 走 pipefifo_fops:
3.3 private_data —— struct file 的变形金刚
private_data 是 struct file 最强大的字段——它让"一个通用描述符"能承担 pipe、socket、epoll、eventfd 等完全不同的语义:
| 文件类型 | private_data 指向 | 通过哪个函数创建 |
|---|---|---|
| pipe | struct pipe_inode_info*(环形缓冲区、读写头) | pipe() → do_pipe2() |
| socket | struct socket*(协议族、类型、sock 指针) | socket() → sock_alloc_file() |
| epoll | struct eventpoll*(红黑树 + 就绪链表) | epoll_create1() |
| eventfd | struct eventfd_ctx*(64 位计数器 + 等待队列) | eventfd() |
| timerfd | struct timerfd_ctx*(定时器到期时间) | timerfd_create() |
| signalfd | struct signalfd_ctx*(信号掩码 + 环形缓冲区) | signalfd() |
| inotify | struct fsnotify_group*(监控项列表) | inotify_init1() |
这就是为什么你能 epoll 监控 pipe、socket、eventfd——它们底层都是 struct file,只不过 private_data 各不相同,f_op->poll 各自实现了自己的等待逻辑。
3.4 f_count 引用计数 —— struct file 何时释放
f_count 控制 struct file 的生命周期,与 files_struct 的 count 是两个维度:
f_count 归零时发生什么(__fput):
fput(file)
  → if atomic_dec_and_test(&file->f_count):       // 最后一个引用
        __fput(file)
          → eventpoll_release(file)                // ① 从所有 epoll 监控中移除
          → if file->f_op->release:
                file->f_op->release(inode, file)   // ② 调用文件类型的 release(如 sock_close)
          → dput(file->f_path.dentry)              // ③ 释放 dentry 引用
          → mntput(file->f_path.mnt)              // ④ 释放 vfsmount 引用
          → put_cred(file->f_cred)                 // ⑤ 释放 open 时取的凭证
→ kmem_cache_free(filp_cachep, file) // ⑥ free 掉 file 结构体本身关键:
f_count控制的是struct file(会话对象)的释放,不是 inode 的释放。只有所有指向 inode 的struct file都释放了、没有目录项引用了,inode 才可能被 evict。open一次就持有一个 file 引用,所以即使unlink了文件,已打开的 fd 仍然可以继续读写(inode 还在,只是硬链接计数归零)。
四、共享语义 —— dup / fork / 线程 / unix socket fd 传递
4.1 两种独立的引用计数,彻底分清
| 对象 | 引用计数字段 | 谁管理 | 共享粒度 | 归零后果 |
|---|---|---|---|---|
files_struct | files->count | 线程级别 | CLONE_FILES 的线程共享 | 释放 files_struct + fdtable 全部资源 |
struct file | file->f_count | 打开文件级别 | dup / fork / SCM_RIGHTS | 释放 struct file + 调用 release |
这俩独立运作:多个线程共享同一份 files_struct(count=5),但每个 fd 指向的 struct file 各自有不同的 f_count。
4.2 操作矩阵
| 操作 | files_struct | struct file | f_count 变化 | 偏移共享? | 典型场景 |
|---|---|---|---|---|---|
两次 open 同一文件 | 各自新 fd | 不同 file 对象 | 各自 f_count=1 | 否 | 两个进程各自 open 同一个 log |
dup(3)=5 / dup2(3,5) | 新 fd 槽 | 共享同一 file | f_count++ | 是 | dup2(fd, STDOUT_FILENO) 重定向 |
fork | 新建独立一份,fd 数组拷贝 | 条目指向同一批 file | 每个 file 的 f_count 各 +1 | 是 | 父进程打开 log → fork → 父子共享 log 偏移 |
同进程线程 (CLONE_FILES) | 共享同一份 files_struct(count++) | 同一批 | 不变 | 是 | 工作线程池共享 fd |
execve | 保留(CLOEXEC 位图的除外) | 保留(f_count 不变) | 不变 | 是 | fd 默认跨 exec 存活 |
unix socket SCM_RIGHTS | 发送方 fd 表不变,接收方新 fd 槽 | 发送方 file 的 f_count++,接收方 fd 指向同一 file | +1 | 是 | 父进程把 fd 传给工作进程 |
fork 共享偏移的经典坑:父子进程
fork后写同一个继承来的 fd(如都写 log),因为共享struct file的f_pos,写入会接续而非互相覆盖——这通常是想要的;但若各自lseek就会互相干扰。细节见 process-creation §一。
4.3 dup / dup2 / dup3 的内核路径
dup(3)
  → ksys_dup(3)
    → fget(3)                          // f_count++ (防止并发 close 释放)
    → alloc_fd(0, 0)                   // 从 0 开始找空闲 fd
    → fd_install(newfd, file)          // fdt->fd[newfd] = file
    → fput(file)                       // f_count-- (平衡之前的 fget)
dup2(3, 0)    // 把 fd 3 dup 到 fd 0 (stdin)
  → ksys_dup3(3, 0, 0)
    → 如果 0 已占用: __close_fd(0)    // 先关闭目标 fd
    → fget(3)
    → fd_install(0, file)
dup3(3, 0, O_CLOEXEC)
  → 同上,但额外设置 close_on_exec 位
4.4 fork 复制 fd 表的内核路径
fork() → copy_process()
  → copy_files(clone_flags, tsk)
    → if CLONE_FILES:
          get_files_struct(old)         // 共享: count++
          task->files = old
      else:
          dup_fd(old_files, &error)
            → 分配新 files_struct + 拷贝 fdtable
            → 遍历 fd 数组: 每个非 NULL 的 entry:
                new_fdt->fd[i] = old_fdt->fd[i]
                get_file(file)           // f_count++  ← 关键
五、close-on-exec —— fd 的"死亡开关"
5.1 为什么需要
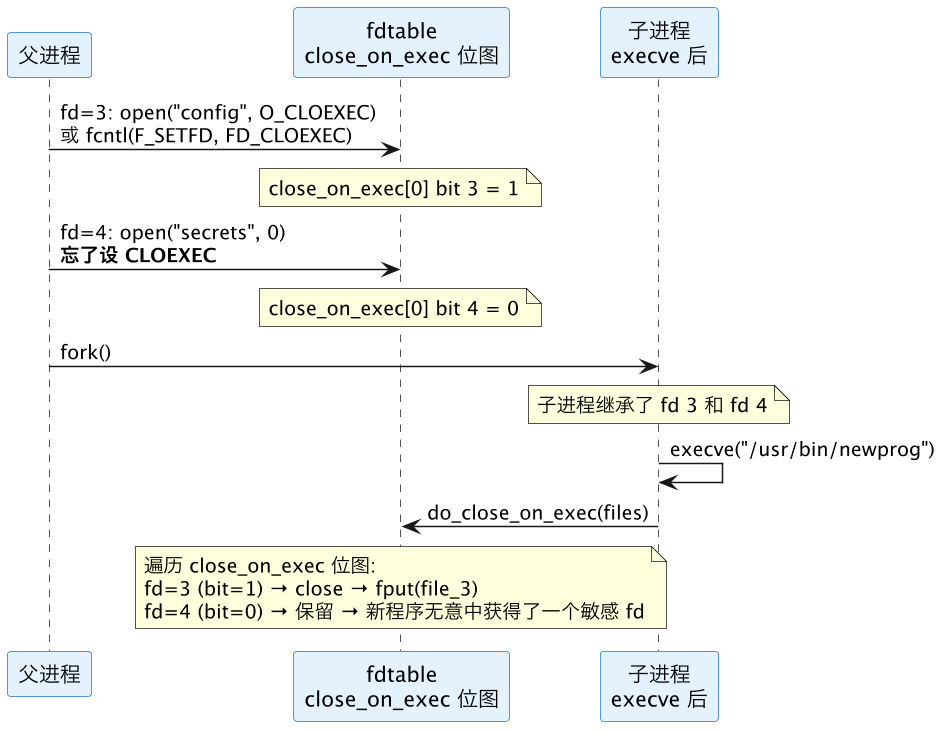
fork + execve 是 Unix 创建进程的唯一方式。如果父进程打开了 10000 个 fd,子进程 execve 一个新程序时,这 10000 个 fd 会原封不动继承过去——新程序既不知道也不该拥有这些 fd(安全风险 + 资源泄漏)。
close_on_exec 位图就是解决这个问题的:在 fd 表里给每个 fd 打一个标记——execve 时,"打了勾的 fd 自动关闭"。
5.2 实现
execve 调用栈中关键一步:
execve()
  → do_execveat_common()
    → bprm_execve()
      → exec_binprm()
        → search_binary_handler()
          → load_elf_binary()
            → begin_new_exec()
              → do_close_on_exec(current->files)
                → 遍历 files->fdt->close_on_exec 位图
                → 对每个置位的 fd:
                    __close_fd(current->files, fd)
5.3 最佳实践
| 方式 | 代码 | 说明 |
|---|---|---|
| 打开时设置 | open(path, O_RDONLY | O_CLOEXEC) | 推荐——创建 fd 时原子设置,避免 TOCTOU 竞态 |
| 打开后设置 | fcntl(fd, F_SETFD, FD_CLOEXEC) | 不推荐——open 和 fcntl 之间有窗口期(另一个线程可能在此间隙 fork+execve) |
O_CLOEXEC 的原子性:
open(..., O_CLOEXEC)在内核一次系统调用内完成"分配 fd + 设置 close_on_exec 位",不存在竞态窗口。open+fcntl两步走有被多线程 race 的风险。
六、fd 上限与泄漏
6.1 三层限制
| 限制层 | 变量 | 查看方式 | 含义 |
|---|---|---|---|
| 进程级 | RLIMIT_NOFILE | ulimit -n / /proc/<pid>/limits | 本进程最多开多少个 fd。默认通常 1024 |
| 系统级(fd) | fs.nr_open | /proc/sys/fs/nr_open | RLIMIT_NOFILE 可设的最大值。默认 1048576 |
| 系统级(file) | fs.file-max | /proc/sys/fs/file-max | 全系统 struct file 总数上限。默认根据内存自动计算 |
# 调大进程级限制
ulimit -n 1048576
# 查看系统级状态
cat /proc/sys/fs/file-nr
# 输出: 已分配数  未用数  最大值(file-max)
#   → 已分配数接近最大值 = 系统 fd 紧张
cat /proc/sys/fs/file-max
# 全系统 file 总数上限
6.2 fd 泄漏的检测信号
fd 泄漏:open/socket/pipe/accept 之后忘了 close,fd 表越来越满,最终 open 返回 EMFILE(Too many open files)。
检测方法:
# 1. 看某个进程当前开了多少 fd
ls /proc/<pid>/fd | wc -l
# 2. 持续监控 fd 数变化——如果只涨不跌 = 泄漏
watch -n 1 "ls /proc/<pid>/fd | wc -l"
# 3. 用 lsof 看具体开了什么
lsof -p <pid> | awk '{print $9}' | sort | uniq -c | sort -rn | head -20
# 4. 系统级:看 file-nr 的第一列是否在持续增长(不下降)
watch -n 1 'cat /proc/sys/fs/file-nr'
C10K/C100K 服务器的特殊考量:一个连接消耗 1 个 fd(socket),高并发服务器必须确保 ulimit -n 远大于预期并发连接数。同时注意:accept 返回的 fd 也要设 SOCK_CLOEXEC(或 accept4(..., SOCK_CLOEXEC))。
七、生命周期
7.1 进程创建时的 files_struct
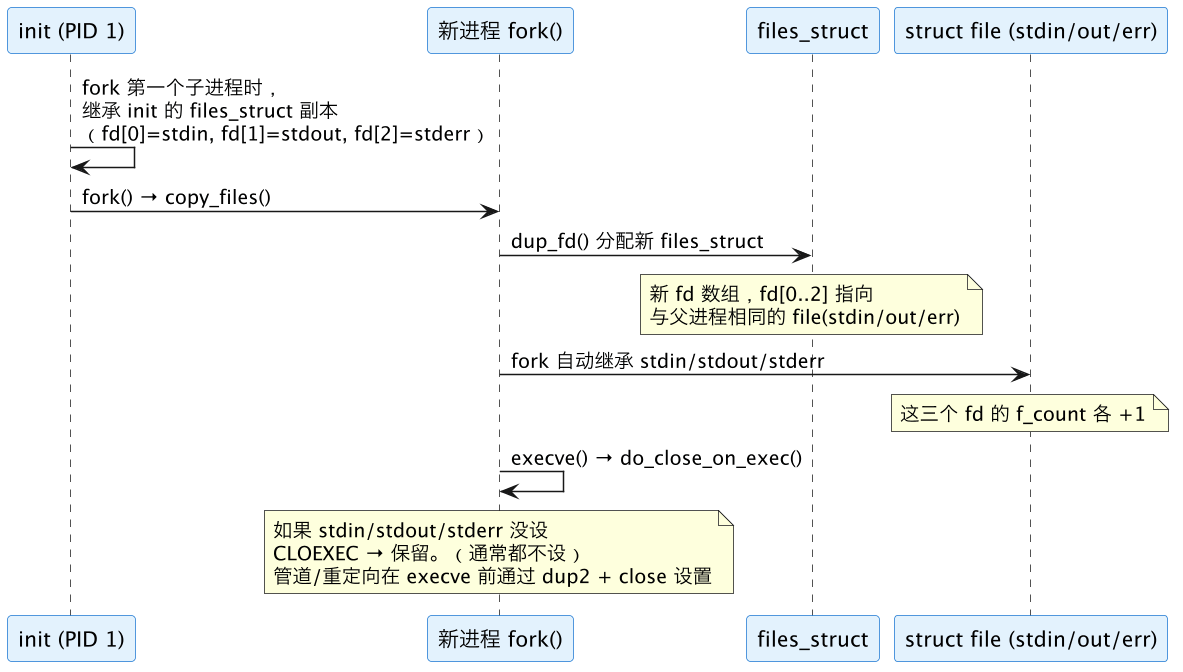
7.2 进程退出时的清理
do_exit()
  → exit_files(tsk->files)
    → put_files_struct(files)           // count--,如果 count 归零:
        → close_files(files)
          → for each fd in fdt->fd:
                if fd[i] != NULL:
                    filp_close(fd[i])  // → fput(file)
          → free_fdtable(fdt)           // 释放 fd 数组、close_on_exec、full_fds_bits
→ kmem_cache_free(files) // 释放 files_struct 本身注意退出顺序:do_exit 先关所有 fd(exit_files),再释放 mm(exit_mm)。因为内存映射中可能有文件映射(file-backed mmap),关闭 fd 时需要先处理这些映射。
7.3 关键状态转换
进程 A (单线程)
  files_struct count=1
  → 线程 B 创建 (CLONE_FILES): count=2, 共享同一份
  → 线程 B 退出 (put_files_struct): count=1
  → 进程 A 退出 (put_files_struct): count=0 → 触发 close_files
进程 A (单线程)
  files_struct count=1
  → fork 子进程 B: A 的 f_count 不变, B 有独立 files_struct (count=1)
  → A 某 fd 对应的 f_count 各 +1 (子进程也指着)
  → B close(fd): f_count-- (仅 B 侧的 fd 槽释放)
  → A close(fd): f_count-- → 归零 → __fput 释放 struct file
八、观测
# 基础:看某个进程开了哪些 fd
ls -l /proc/<pid>/fd/
# 输出示例:
# 0 -> /dev/pts/0          (stdin)
# 1 -> /dev/pts/0          (stdout)
# 3 -> /var/log/app.log    (普通文件 → inode)
# 4 -> socket:[12345]      (socket → inode 号)
# 5 -> pipe:[67890]        (管道 → inode 号)
# 7 -> anon_inode:[eventfd]
# 8 -> anon_inode:[eventpoll] (epoll)
# 精确到 fd 细节
lsof -p <pid>             # fd、类型、大小、偏移、文件名
# 系统级文件描述符水位
cat /proc/sys/fs/file-nr  # 已分配 未用 上限
# 统计全系统各类型 open file
lsof | awk '{print $5}' | sort | uniq -c | sort -rn | head -10
# 哪类 fd 异常多
ls -l /proc/<pid>/fd | awk '{print $NF}' | sort | uniq -c | sort -rn
/proc/<pid>/fd/ 里每个符号链接的目标揭示了 fd 的真实面目:
| 目标格式 | fd 类型 |
|---|---|
/path/to/file | 普通文件(磁盘上的 inode) |
socket:[数字] | socket(数字是 inode 号) |
pipe:[数字] | 管道 |
anon_inode:[eventfd] / [eventpoll] / [timerfd] | eventfd / epoll / timerfd |
/dev/xxx | 设备节点 |
anon_inode:[signalfd] | signalfd |
anon_inode:inotify | inotify |
九、和其它文档的关系
- 父篇:task-struct(files 是 task 的资源对象之一)。
- VFS 视角:vfs-from-process —— 从进程到 VFS 的五跳链路全解析:
task_struct → files_struct → fdtable → struct file → f_op。 - 文件操作:vfs-file-operations ——
struct file_operations的方法详解。 - 创建时共享/复制:process-creation(fork 复制 fd 表、共享 file 偏移)、thread-creation(线程共享 files_struct)。
- socket 内核实现:socket-kernel-internals ——
socket()如何创建struct file并填入private_data。 - epoll:epoll —— epoll fd 的
struct file.private_data=eventpoll*,以及file->f_ep链表。 - 观测:lsof(lsof 看 fd)、procfs(
/proc/<pid>/fd)。
十、一句话总结
files_struct是进程的 fd 表容器,内核要点只有三个:fd 数组怎么找空闲位(next_fd缓存 +full_fds_bits跳跃 → 绝大多数情况 O(1))、满了怎么扩容(expand_fdtable至少翻倍,多线程共享时先 COW 分裂再扩)、struct file怎么管理生命周期(f_count引用计数——open/dup/fork/scm_rights 各 +1,close/exit 各 -1,归零时__fput:注销 epoll → 调 release → 释放 dentry/mnt/cred → free file)。两层引用计数永远分清:files_struct->count管 fd 表的线程共享,file->f_count管会话对象的跨进程共享。偏移f_pos在 file 这一层,所以 dup/fork 共享偏移、两次 open 独立偏移。close_on_exec位图保护 fd 跨 execve 泄漏,O_CLOEXEC原子设置避免竞态。private_data让同一个struct file成为 pipe/socket/epoll/eventfd/inotify 的统一载体。透过/proc/<pid>/fd/、lsof、/proc/sys/fs/file-nr三刀观测。