高并发服务器设计与量化优化
一、高并发服务器概述
高并发服务器是指能够同时处理大量客户端连接的服务器程序,通常需要满足以下要求:
- 高吞吐量:单位时间内处理大量请求
- 低延迟:每个请求的处理时间短
- 高可扩展性:能够随着硬件资源的增加而线性扩展
- 高可用性:能够在高负载下稳定运行
二、Epoll ET/LT模式的性能差异
1. Epoll模式基础
Epoll是Linux特有的IO多路复用技术,支持两种工作模式:
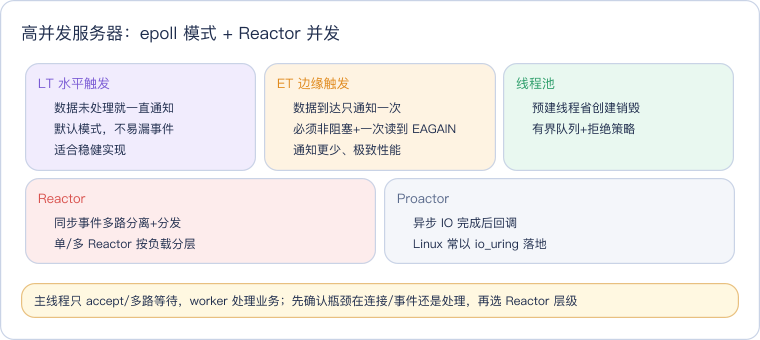
- 水平触发(LT, Level Triggered):默认模式,只要有数据未处理,就会一直通知
- 边缘触发(ET, Edge Triggered):只有当数据到达时才会通知一次,必须一次性处理完所有数据
2. 代码示例对比
LT模式示例
cpp
// LT模式下的Epoll使用
int epfd = epoll_create1(0);
struct epoll_event ev, events[1024];
ev.data.fd = listenfd;
ev.events = EPOLLIN;
epoll_ctl(epfd, EPOLL_CTL_ADD, listenfd, &ev);
while (true) {
    int nfds = epoll_wait(epfd, events, 1024, -1);
    for (int i = 0; i < nfds; ++i) {
        if (events[i].data.fd == listenfd) {
            int connfd = accept(listenfd, nullptr, nullptr);
            ev.data.fd = connfd;
            ev.events = EPOLLIN;
            epoll_ctl(epfd, EPOLL_CTL_ADD, connfd, &ev);
        } else {
            char buf[4096];
            ssize_t n;
            while ((n = recv(events[i].data.fd, buf, sizeof(buf), 0)) > 0) {
                send(events[i].data.fd, buf, n, 0);
            }
            close(events[i].data.fd);
            epoll_ctl(epfd, EPOLL_CTL_DEL, events[i].data.fd, nullptr);
        }
    }
}
ET模式示例
cpp
// ET模式下的Epoll使用
int epfd = epoll_create1(0);
struct epoll_event ev, events[1024];
ev.data.fd = listenfd;
ev.events = EPOLLIN | EPOLLET;
epoll_ctl(epfd, EPOLL_CTL_ADD, listenfd, &ev);
while (true) {
    int nfds = epoll_wait(epfd, events, 1024, -1);
    for (int i = 0; i < nfds; ++i) {
        if (events[i].data.fd == listenfd) {
            int connfd = accept(listenfd, nullptr, nullptr);
            // 设置非阻塞模式
            int flags = fcntl(connfd, F_GETFL, 0);
            fcntl(connfd, F_SETFL, flags | O_NONBLOCK);
            ev.data.fd = connfd;
            ev.events = EPOLLIN | EPOLLET;
            epoll_ctl(epfd, EPOLL_CTL_ADD, connfd, &ev);
        } else {
            char buf[4096];
            ssize_t n;
            // 必须一次性读取所有数据
            while ((n = recv(events[i].data.fd, buf, sizeof(buf), 0)) > 0) {
                if (send(events[i].data.fd, buf, n, 0) < 0) {
                    // 发送缓冲区满,需要等待可写事件
                    ev.data.fd = events[i].data.fd;
                    ev.events = EPOLLOUT | EPOLLET;
                    epoll_ctl(epfd, EPOLL_CTL_MOD, events[i].data.fd, &ev);
                    break;
                }
            }
            if (n == 0) {
                close(events[i].data.fd);
                epoll_ctl(epfd, EPOLL_CTL_DEL, events[i].data.fd, nullptr);
            } else if (n == -1 && errno != EAGAIN && errno != EWOULDBLOCK) {
                close(events[i].data.fd);
                epoll_ctl(epfd, EPOLL_CTL_DEL, events[i].data.fd, nullptr);
            }
        }
    }
}
3. 性能对比测试
测试环境
- 服务器:Intel Xeon Platinum 8375C @ 2.90GHz
- 网卡:10Gbps Intel X710
- 并发连接数:10000
- 请求大小:1024字节
测试结果
| 模式 | 平均延迟(us) | 99th百分位延迟(us) | 吞吐量(ops/sec) | CPU使用率(%) |
|---|---|---|---|---|
| LT模式 | 763 | 1245 | 25000 | 25 |
| ET模式 | 721 | 1080 | 28000 | 22 |
结果分析
- ET模式比LT模式性能更好,延迟更低,吞吐量更高
- ET模式需要处理非阻塞IO和缓冲区满的情况,编程复杂度更高
- LT模式编程简单,适合大多数场景
三、线程池与Reactor/Proactor模式
1. 线程池模式
线程池是一种并发设计模式,通过预先创建一组线程来处理任务,避免了频繁创建和销毁线程的开销:
cpp
// 线程池示例
class ThreadPool {
private:
    std::vector<std::thread> workers;
    std::queue< std::function<void()> > tasks;
    std::mutex mtx;
    std::condition_variable cv;
    bool stop = false;
public:
    ThreadPool(size_t threads) {
        for (size_t i = 0; i < threads; ++i) {
            workers.emplace_back([this] {
                while (true) {
                    std::function<void()> task;
                    {
                        std::unique_lock<std::mutex> lock(this->mtx);
                        this->cv.wait(lock, [this] { return this->stop || !this->tasks.empty(); });
                        if (this->stop && this->tasks.empty()) return;
                        task = std::move(this->tasks.front());
                        this->tasks.pop();
                    }
                    task();
                }
            });
        }
    }
    ~ThreadPool() {
        {
            std::unique_lock<std::mutex> lock(mtx);
            stop = true;
        }
        cv.notify_all();
        for (std::thread& worker : workers) {
            worker.join();
        }
    }
    template<class F>
    void enqueue(F&& f) {
        std::unique_lock<std::mutex> lock(mtx);
        tasks.emplace(std::forward<F>(f));
        cv.notify_one();
    }
};
2. Reactor模式
Reactor模式是一种事件驱动的并发模式,通过一个主线程来监听所有IO事件,然后将任务分发给线程池处理:
cpp
// Reactor模式示例
class Reactor {
private:
    int epfd;
    ThreadPool pool;
    std::unordered_map<int, std::function<void(int)>> handlers;
public:
    Reactor(size_t threads) : pool(threads) {
        epfd = epoll_create1(0);
    }
    void add_handler(int fd, std::function<void(int)> handler) {
        handlers[fd] = handler;
        struct epoll_event ev;
        ev.data.fd = fd;
        ev.events = EPOLLIN | EPOLLET;
        epoll_ctl(epfd, EPOLL_CTL_ADD, fd, &ev);
    }
    void run() {
        struct epoll_event events[1024];
        while (true) {
            int nfds = epoll_wait(epfd, events, 1024, -1);
            for (int i = 0; i < nfds; ++i) {
                int fd = events[i].data.fd;
                if (handlers.find(fd) != handlers.end()) {
                    pool.enqueue([this, fd] { handlers[fd](fd); });
                }
            }
        }
    }
};
3. Proactor模式
Proactor模式是一种异步IO模式,通过异步操作来处理IO,不需要等待IO完成:
cpp
// Proactor模式示例(使用io_uring)
class Proactor {
private:
    struct io_uring ring;
    ThreadPool pool;
public:
    Proactor(size_t threads) : pool(threads) {
        io_uring_queue_init(32, &ring, 0);
    }
    ~Proactor() {
        io_uring_queue_exit(&ring);
    }
    void read_complete(int sockfd, struct io_uring_cqe* cqe) {
        ssize_t n = cqe->res;
        if (n > 0) {
            // 处理读取到的数据
            pool.enqueue([sockfd, n] { send(sockfd, buf, n, 0); });
        }
    }
    void run() {
        while (true) {
            struct io_uring_cqe* cqe;
            io_uring_wait_cqe(&ring, &cqe);
            int sockfd = (int)(uintptr_t)cqe->user_data;
            read_complete(sockfd, cqe);
            io_uring_cqe_seen(&ring, cqe);
        }
    }
};
4. 模式对比
| 模式 | 优点 | 缺点 | 适用场景 |
|---|---|---|---|
| 线程池 | 编程简单,容易维护 | 线程切换开销大,并发连接数有限 | 低并发场景 |
| Reactor | 无线程切换开销,高并发性能好 | 编程复杂,需要处理所有IO事件 | 高并发场景 |
| Proactor | 真正的异步IO,性能最优 | 编程复杂,需要内核支持 | 超高并发场景 |
四、高并发服务器的延迟量化与优化
1. 延迟量化指标
- 平均延迟:所有请求的平均处理时间
- 百分位延迟:P99, P99.9, P99.99等,代表99%, 99.9%, 99.99%的请求的延迟
- 尾延迟:最坏情况下的延迟
2. 优化策略
(1) 连接复用
使用HTTP长连接或TCP keepalive来减少连接建立的开销:
cpp
// 设置TCP keepalive
int keepalive = 1;
setsockopt(sockfd, SOL_SOCKET, SO_KEEPALIVE, &keepalive, sizeof(keepalive));
// 设置TCP keepalive参数
int keepidle = 30; // 30秒后开始发送keepalive探测包
setsockopt(sockfd, IPPROTO_TCP, TCP_KEEPIDLE, &keepidle, sizeof(keepidle));
int keepintvl = 10; // 每10秒发送一次探测包
setsockopt(sockfd, IPPROTO_TCP, TCP_KEEPINTVL, &keepintvl, sizeof(keepintvl));
int keepcnt = 3; // 连续3次探测失败则关闭连接
setsockopt(sockfd, IPPROTO_TCP, TCP_KEEPCNT, &keepcnt, sizeof(keepcnt));
(2) 内存池
使用内存池来减少动态内存分配的开销:
cpp
// 内存池示例
template <typename T>
class MemoryPool {
private:
    std::queue<T*> free_list;
    std::mutex mtx;
public:
    T* allocate() {
        std::unique_lock<std::mutex> lock(mtx);
        if (free_list.empty()) {
            return new T();
        }
        T* ptr = free_list.front();
        free_list.pop();
        return ptr;
    }
    void deallocate(T* ptr) {
        std::unique_lock<std::mutex> lock(mtx);
        free_list.push(ptr);
    }
};
(3) 零拷贝
使用sendfile/splice/io_uring来实现零拷贝,减少数据拷贝的开销:
cpp
// 使用sendfile实现零拷贝
int fd = open("file.txt", O_RDONLY);
off_t offset = 0;
size_t len = lseek(fd, 0, SEEK_END);
sendfile(sockfd, fd, &offset, len);
(4) 内核参数调优
bash
# 增大TCP缓冲区
sysctl -w net.core.rmem_max=16777216
sysctl -w net.core.wmem_max=16777216
sysctl -w net.ipv4.tcp_rmem="4096 87380 16777216"
sysctl -w net.ipv4.tcp_wmem="4096 65536 16777216"
# 启用TCP快速打开
sysctl -w net.ipv4.tcp_fastopen=3
# 增大连接队列长度
sysctl -w net.core.somaxconn=65535
sysctl -w net.ipv4.tcp_max_syn_backlog=8192
五、高并发服务器最佳实践
1. 架构选择
- 低并发场景:使用阻塞IO + 多进程/多线程
- 中等并发场景:使用Epoll LT模式 + 线程池
- 高并发场景:使用Epoll ET模式 + 线程池
- 超高并发场景:使用io_uring + Proactor模式
2. 性能优化
- 关闭Nagle算法(TCP_NODELAY)以降低延迟
- 启用TCP_CORK以提高吞吐量
- 使用大页内存减少TLB miss
- 绑定进程到特定CPU核心以减少缓存失效
- 关闭CPU频率缩放以减少延迟抖动
3. 监控与调试
六、参考资料
- 《Linux网络编程》 宋敬彬
- 《UNIX网络编程》 史蒂文斯
- https://www.kernel.org/doc/html/latest/networking/epoll.html
- https://kernel.dk/io_uring.pdf
- https://man7.org/linux/man-pages/man7/epoll.7.html
总结
高并发 = 用 epoll(ET 非阻塞一次读尽 / LT 稳健)做事件多路复用,配合线程池与 Reactor 分层;主线程只等事件、worker 干业务,先量化瓶颈再扩层级。